YaCy: Running Your Own Decentralised Search Engine
What happens when there is no single organisation that can be pressured to remove a result, hand over a search history or quietly change what an entire population is able to find?
Most of us use a search engine without thinking very much about what happens behind the search box. You type a query, press Enter and somebody else's infrastructure decides what you see.
Google, Bing and the other large search providers have become such a normal part of the Internet that the idea of actually running your own search engine sounds slightly ridiculous. It turns out it isn't.
YaCy, an open-source search engine that can run entirely on your own hardware and, if you choose, become part of a decentralised peer-to-peer search network.
And that's where it gets interesting.
The darker side of search
There is also a less comfortable reason why decentralised search is interesting. Search engines are not simply technical conveniences; they are gateways to information. Whoever controls the index, the ranking system and access to it has considerable influence over what can be discovered and what effectively disappears from view.
In more restrictive environments, concerns can extend beyond simple content filtering into censorship, surveillance, profiling, political monitoring, investigative journalism and the tracking of activists or dissidents. A decentralised system such as YaCy raises an intriguing question: what happens when there is no single organisation that can be pressured to remove a result, hand over a search history or quietly change what an entire population is able to find?
That does not make decentralised technology immune from abuse, nor does it guarantee anonymity, but it makes the underlying architecture worth thinking about. The same tools that can preserve access to information can also be used irresponsibly, so anyone experimenting with them should understand the legal, ethical and security implications.
The history of the Internet suggests that control of information eventually becomes a question of power. Decentralised search is interesting precisely because it asks what happens when that power is no longer concentrated in one place.
This article is provided for information, research and entertainment purposes only.
So that said, what is YaCy?
YaCy is both a search engine and a web crawler. A normal search engine essentially consists of three important components:
Crawler → Index → Search interface
The crawler discovers web pages, the index stores information about those pages and the search interface lets you query the resulting database. YaCy gives you all three.
But unlike Google or Bing, there doesn't have to be one enormous central index.
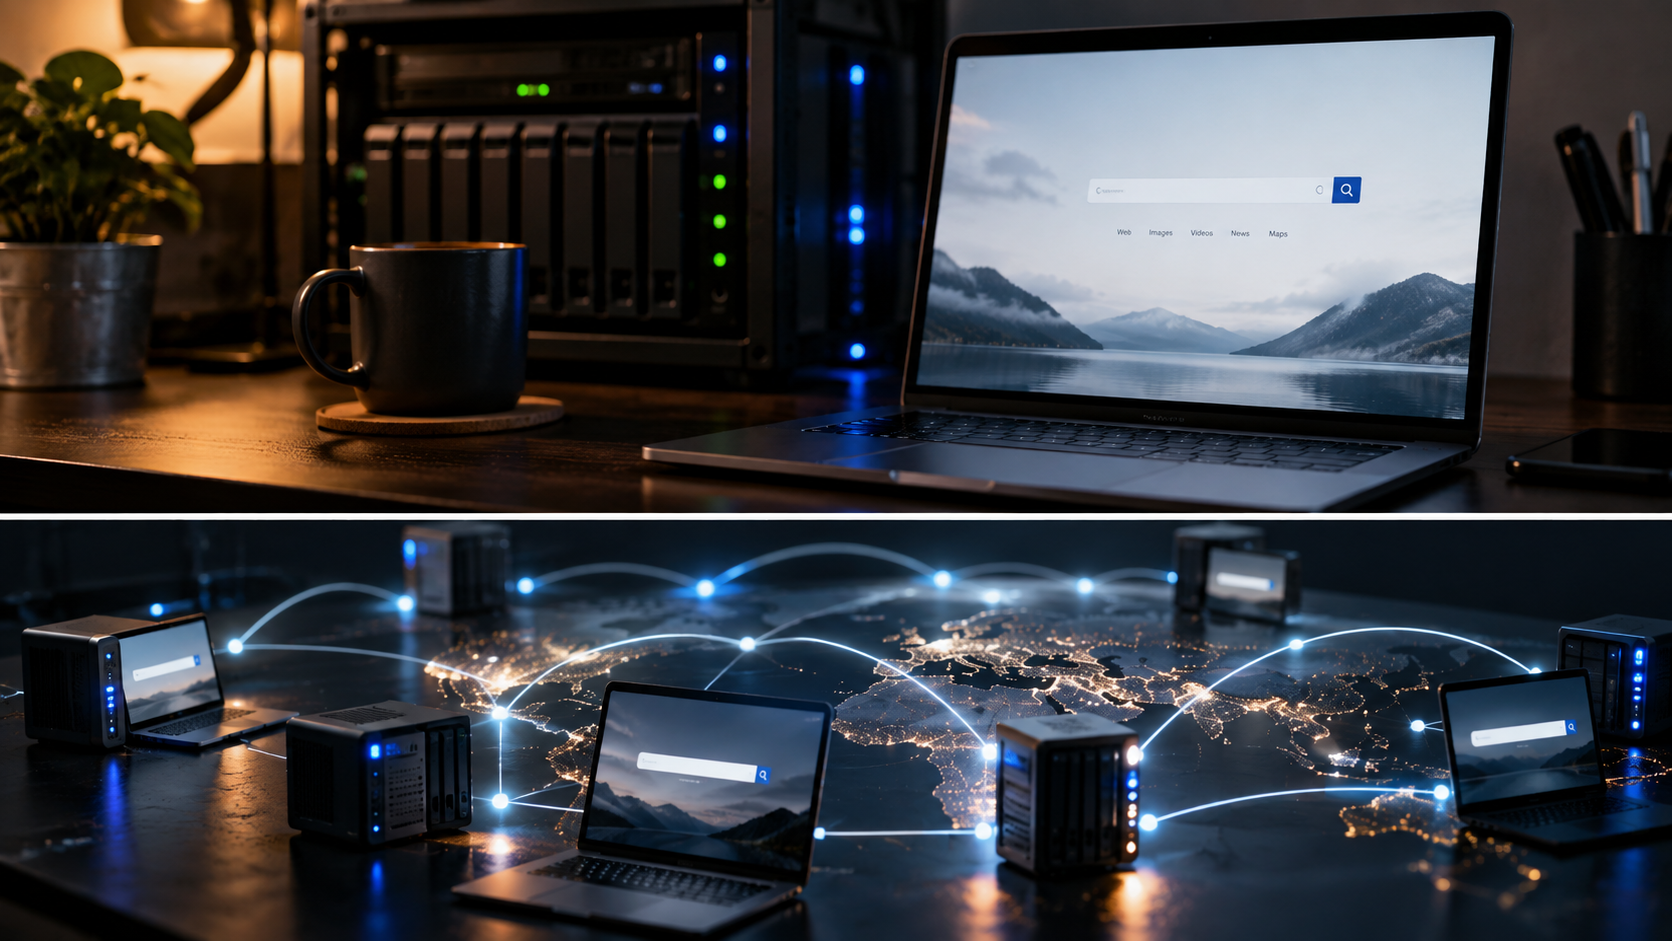
YaCy can operate as an independent search engine with its own local index, or it can join a peer-to-peer network of other YaCy installations and participate in a distributed search index. YaCy
That immediately opens up several interesting possibilities.
You could use it as:
- your own private search engine;
- a search engine for a particular collection of websites;
- an internal company or intranet search engine;
- a crawler and index for research;
- or a peer in a decentralised public search network.
It can also search local or organisational content rather than being limited purely to the public Internet. YaCy
For someone who likes self-hosting, that is quite an appealing proposition.
Why bother running a search engine?
The obvious question is:
Why would I run this when Google already exists?
Because the interesting part isn't necessarily replacing Google.
It is having control of the index.
With YaCy I can decide what gets crawled and indexed. I can create a search engine around a particular subject, collection of sites or internal environment rather than depending entirely on an external provider.
There is also the privacy aspect.
YaCy was designed with privacy as one of its motivations, and in local-search mode searches can be performed against your own index without sending the query to a conventional central search provider. GitHub
That doesn't automatically make every possible YaCy configuration "private" — particularly if you choose to participate in the public P2P network — but it does give the person running it considerably more control over where searches go and where the index lives.
And, frankly, sometimes the best reason to self-host something is simply: because you can.
Local Search or Decentralised Search?
This is probably the most interesting part of YaCy. You don't actually have to participate in the public network. YaCy supports several distinct use cases.
A private search engine
YaCy can maintain its own index. You tell it where to crawl, it builds the index and searches stay within that environment. That could be particularly useful for documentation, research material or a collection of sites around a specific subject.
An intranet search engine
YaCy can also be used to index internal resources and build an organisation-specific search portal. Its project documentation explicitly positions this as one of YaCy's use cases. GitHub
That's potentially interesting from a business perspective.
Imagine an organisation with:
Wiki
SharePoint
Documentation
Internal websites
Knowledge bases
File servers
Technical portals
Rather than employees having to know where everything lives, an internal search layer can sit above the information.
The public YaCy network
And finally there's Freeworld, YaCy's public community network.
YaCy peers can exchange search-index information through the built-in peer-to-peer system rather than relying upon one central search provider. The project's current default network configuration identifies this public network as freeworld. GitHub
Conceptually it changes the model from:
                Google
                  │
        ┌─────────┼─────────┐
        ▼         ▼         ▼
      User      User      User
to something closer to:
      Peer ───── Peer
       │  \      / │
       │   \    /  │
       │    \  /   │
      Peer ───── Peer
       │          │
      Peer ───── Peer
There isn't one central search index owned by one search company. Each participant can contribute.
Don't Expect Google
There is an important caveat.
Installing YaCy does not suddenly give you a home-hosted version of Google.
Google has spent decades crawling an almost incomprehensibly large portion of the web, ranking it using enormous amounts of infrastructure and continually refining the results.
That's not what a small YaCy instance is competing with.
And I don't think that's really the point. The interesting comparison isn't:
Is YaCy better than Google?
It's:
What becomes possible if I control my own crawler and search index?
That is a much more interesting question. I can decide what gets indexed. I can crawl sites that matter to me. I can experiment with specialised indexes. I can run searches locally. I can expose my own search portal. And, if I choose, my server can participate in a decentralised network rather than simply consuming somebody else's search service.
Final thoughts
YaCy is one of those open-source projects that reminds you what the Internet can be. It isn't just another alternative front-end to somebody else's search engine.
It is an actual search engine. Crawler, Indexer, Search server. And optionally a node in a decentralised search network. You can run it yourself. You decide what it indexes. You decide whether it talks to the wider network.
And the whole thing can sit in a Docker container on a machine in the corner of the room.